The 2:00 AM Incident: When Servers Are Green but Services Are Dead
At 2:15 AM, PagerDuty alerts started firing non-stop as the payment gateway threw a flood of 502 Bad Gateway errors. A quick glance at the infrastructure dashboard showed everything looking completely healthy: total cluster CPU usage hovered around 18%, more than half the RAM was free, and disk I/O remained stable.
Yet checking the production pods told a very different story:
kubectl get pods -n production -l app=payment-serviceAll four payment service pods were stuck in CrashLoopBackOff. Restart counts had spiked to 37 within 30 minutes due to Out Of Memory (OOMKilled) errors. Meanwhile, over in the staging namespace, a newly updated deployment sat at 0/3 available pods for over two hours without anyone noticing. The staging namespace had hit its CPU ResourceQuota ceiling, causing the Kubernetes Scheduler to silently reject new scheduling requests.
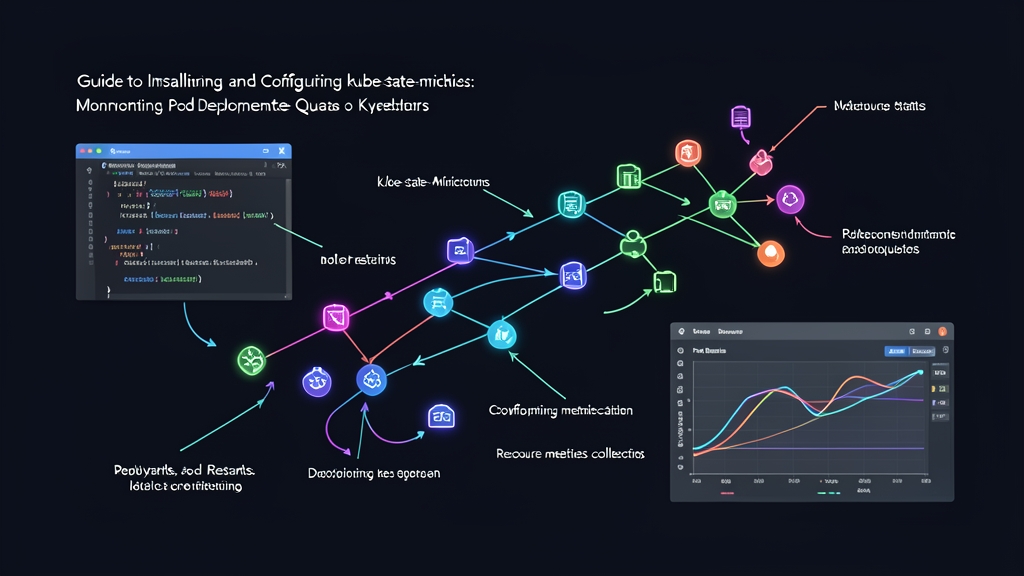
The lesson here is simple: tools like node-exporter or cAdvisor only measure hardware resource consumption. They cannot tell you anything about the logical state of Kubernetes objects. To track pod restarts, deployment replica drift, or namespace resource quotas, you need kube-state-metrics.
How Does kube-state-metrics Work?
Within the Kubernetes monitoring ecosystem, different tools operate across distinct layers:
- cAdvisor / metrics-server: Measures actual resource utilization (CPU millicores, RAM megabytes, network I/O bytes) consumed by containers. This data powers the
kubectl topcommand and Horizontal Pod Autoscalers (HPA). - kube-state-metrics (KSM): Connects directly to the Kubernetes API Server using the
client-gowatch mechanism. KSM does not measure real-time CPU or RAM consumption. Instead, it reflects the declarative state and health status of objects: whether a pod is Pending or Running, container restart counts, whether deployments have enough available replicas, and the percentage of resource quotas consumed.
KSM translates this metadata into standard Prometheus metrics exposed on port :8080/metrics, ready for Prometheus to scrape on schedule, complementing specialized tools like OpenCost for Kubernetes cost allocation and capacity tracking.
3 Critical Metric Groups for Your Dashboards
kube_pod_container_status_restarts_total: Tracks total container restarts. This serves as an early indicator of memory leaks or application panics caused by unhandled exceptions.kube_deployment_status_replicas_availableandkube_deployment_spec_replicas: Measures the gap between actual pods serving live traffic and desired replicas defined in your YAML manifests.kube_resourcequota: Monitors namespace-level resource consumption, preventing clusters from silently blocking new pod scheduling.
Step-by-Step Installation and Configuration of kube-state-metrics
Instead of manually running kubectl describe during an outage, you can deploy KSM via Helm and set up automated alerting rules in minutes.
Step 1: Install kube-state-metrics Using Helm
Use the official chart maintained by the Prometheus Community to deploy KSM into your cluster:
# Add the official repository
helm repo add prometheus-community https://prometheus-community.github.io/helm-charts
helm repo update

# Deploy into the kube-system namespace
helm install kube-state-metrics prometheus-community/kube-state-metrics \
  --namespace kube-system \
  --set replicas=1 \
  --set metricLabelsAllowlist.pods="[app,version,tier]"
The metricLabelsAllowlist.pods parameter allows you to whitelist specific labels to retain. By default, KSM drops labels to prevent high series cardinality. Keep only labels that are critical for filtering alerts, such as app or version, especially if you rely on automated pod restarts with Reloader during rolling configuration updates.
Step 2: Verify Metric Output
First, verify that the KSM pod is running smoothly:
kubectl get pods -n kube-system -l app.kubernetes.io/name=kube-state-metricsOnce the pod reaches the Running state, set up a local port forward to inspect the metric stream:
kubectl port-forward -n kube-system svc/kube-state-metrics 8080:8080In another terminal window, run curl:
curl -s http://localhost:8080/metrics | grep kube_pod_container_status_restarts_total | head -n 5You should see sample output similar to:
kube_pod_container_status_restarts_total{container="payment-api",namespace="production",pod="payment-service-789f6d4d5-x8k2l"} 37Step 3: Configure the Prometheus Scrape Job
If you are managing a standalone Prometheus instance, append the following scrape configuration to your prometheus.yml file:
scrape_configs:
  - job_name: 'kube-state-metrics'
    static_configs:
      - targets: ['kube-state-metrics.kube-system.svc.cluster.local:8080']
    scrape_interval: 30s
After reloading Prometheus, navigate to Status > Targets in the Prometheus Web UI to verify target health. The endpoint should display a green UP status.
Step 4: 3 Essential PromQL Queries for Alertmanager
To catch issues before users notice them, configure these three PromQL expressions in your Alertmanager setup, applying techniques from our guide on advanced PromQL query design:
1. Alert on Frequent Container Restarts (> 2 restarts in 15 minutes)
increase(kube_pod_container_status_restarts_total[15m]) > 2The increase() function calculates the net change over the last 15 minutes. If a pod crashes repeatedly due to OOM kills or unhandled runtime panics, this rule fires immediately.
2. Detect Deployments Missing Ready Replicas
(kube_deployment_spec_replicas - kube_deployment_status_replicas_available) > 0This expression detects discrepancies between desired replica counts and pods actually ready to serve traffic, quickly highlighting issues like ImagePullBackOff or failed readinessProbe checks—a method also useful when managing GitOps pipelines like monitoring Argo CD application health and sync status.
3. Alert When CPU Resource Quota Exceeds 85%
kube_resourcequota{type="used", resource="requests.cpu"}
/ on(namespace, resourcequota)
kube_resourcequota{type="hard", resource="requests.cpu"} > 0.85
This expression compares allocated requests against the hard quota limit set for the namespace. Hitting 85% gives operations teams enough lead time to adjust quotas before Kubernetes rejects new workloads.
Conclusion
Kubernetes monitoring cannot stop at raw server-level CPU and RAM metrics. Deploying kube-state-metrics gives you granular visibility into the health of every pod, deployment, and resource quota across your cluster. Setting up these baseline alert rules from day one, or adopting Pyrra to manage SLOs and alerts the Google SRE way, ensures you can address issues proactively before service availability is impacted.