The Latency Nightmare of Traditional Voice AI
Imagine calling an AI customer support line to track an order. You finish asking: “Can you check order 12345 for me?” What follows is a 3-to-5-second silence—so quiet you start wondering if the call dropped.
It gets worse. When the bot starts reciting incorrect information, you quickly cut in to correct it. Unfortunately, it stubbornly barrels through its entire 30-second script before it even considers listening again.
The conversation turns into an awkward, disjointed, and frustrating back-and-forth. It feels nothing like talking to an intelligent assistant.
Root Cause Breakdown: Why Are Voice Bots So Slow?
This 3–5 second lag stems from sequential, batch-processed requests over HTTP:
- Silence Detection: The system waits for 0.7–1.2 seconds of complete silence to confirm you’ve finished speaking.
- Speech-to-Text (STT): The entire audio recording is uploaded to an STT server for transcription (adding 400–800ms).
- LLM Response Generation: The prompt is sent to the LLM. The system waits for the full response to be generated (taking 800–1500ms).
- Text-to-Speech (TTS): The complete text is forwarded to a TTS engine to generate an audio file (adding 600–1000ms).
- Audio Download & Playback: The client downloads the entire MP3/WAV file over HTTP before playback begins.
When you compound network latency with processing time at every step, a sluggish bot is inevitable.
Three Approaches to Real-Time Voice AI
To slash latency from several seconds down to under 800ms (on par with human conversational reflexes), engineers typically consider three approaches:
1. Custom-Built WebSocket API Orchestration
You open parallel WebSocket connections to Deepgram (STT), OpenAI (LLM streaming), and ElevenLabs (TTS streaming). As the user speaks, audio streams continuously; as soon as the LLM yields its first 3–4 tokens, you immediately pipe them into the TTS engine to synthesize chunked audio.
- Pros: Full codebase control without third-party framework dependencies.
- Cons: Extremely complex. You must manually manage stream synchronization, echo cancellation, audio buffering, and barge-in (interruption) logic.
2. Turnkey Commercial Platforms (Vapi, Retell AI)
These SaaS providers offer ready-to-use voice agent infrastructure paired with intuitive dashboards.
- Pros: Fast deployment in just a few hours, with built-in telephony support (Twilio/Vonage).
- Cons: High recurring costs (typically $0.05–$0.15/minute on top of LLM/TTS API fees), vendor lock-in, and limited ability to customize internal logic.
3. Pipecat Powered by WebRTC
An open-source approach that strikes the ideal balance between speed, deep customizability, and cost efficiency.
Pipecat + WebRTC: The Perfect Match for Voice Agents
Pipecat is an open-source Python framework designed specifically for building real-time, multimodal voice and vision agents.
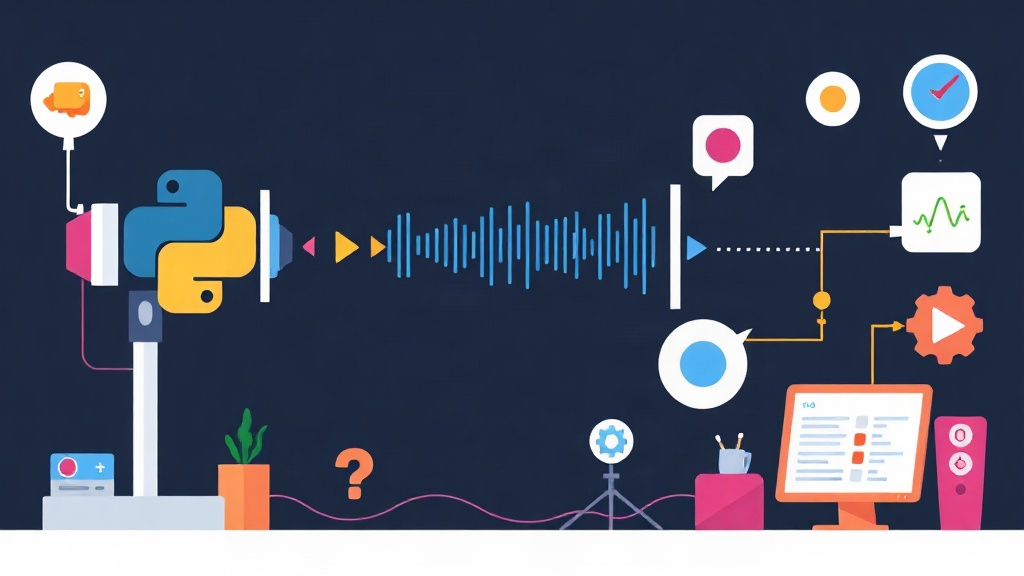
Instead of juggling bulky audio files, Pipecat operates as a streaming pipeline. Audio from the microphone is sliced into ultra-short frames (around 20–40ms) and flows continuously through connected components:
Microphone → Silero VAD → STT (Streaming) → LLM (Tokens) → TTS (Audio Chunks) → Speaker
When paired with WebRTC (via Daily or LiveKit infrastructure), two-way audio transport latency drops to just 50–150ms. More importantly, when a user interrupts (barge-in), the VAD analyzer instantly pushes an interruption frame downstream. The bot immediately stops speaking and pivots to listening to the new input without stalling the pipeline.
Step-by-Step Guide: Building a Voice Agent with Pipecat
Step 1: Environment Setup and Dependencies
Set up a Python 3.10+ virtual environment and install Pipecat along with the required plugins:
# Create and activate virtual environment
python3 -m venv venv
source venv/bin/activate

# Install Pipecat and service connectors
pip install "pipecat-ai[daily,openai,deepgram,silero]" python-dotenv loguru
Create a .env file with your API credentials:
DEEPGRAM_API_KEY=your_deepgram_api_key
OPENAI_API_KEY=your_openai_api_key
DAILY_API_KEY=your_daily_api_key
DAILY_SAMPLE_ROOM_URL=https://yourdomain.daily.co/your-room-name
Step 2: Building the Audio Processing Pipeline
Create a bot.py file with asynchronous handling via asyncio:
import os
import sys
import asyncio
from dotenv import load_dotenv
from loguru import logger

from pipecat.audio.vad.silero import SileroVADAnalyzer
from pipecat.pipeline.pipeline import Pipeline
from pipecat.pipeline.runner import PipelineRunner
from pipecat.pipeline.task import PipelineParams, PipelineTask
from pipecat.processors.aggregators.llm_response import (
    LLMAssistantResponseAggregator,
    LLMUserResponseAggregator,
)
from pipecat.services.deepgram import DeepgramSTTService
from pipecat.services.openai import OpenAILLMService, OpenAITTSService
from pipecat.transports.services.daily import DailyParams, DailyTransport

load_dotenv(override=True)

async def main():
    room_url = os.getenv("DAILY_SAMPLE_ROOM_URL")
    token = os.getenv("DAILY_API_KEY")

    if not room_url:
        logger.error("Please provide DAILY_SAMPLE_ROOM_URL in the .env file")
        sys.exit(1)

    # 1. Initialize WebRTC Transport via Daily
    transport = DailyTransport(
        room_url,
        token,
        "Voice AI Assistant",
        DailyParams(
            audio_out_enabled=True,
            vad_enabled=True,
            vad_analyzer=SileroVADAnalyzer(),
            vad_audio_passthrough=True,
        ),
    )

    # 2. Initialize processing services
    stt = DeepgramSTTService(api_key=os.getenv("DEEPGRAM_API_KEY"))

    llm = OpenAILLMService(
        api_key=os.getenv("OPENAI_API_KEY"),
        model="gpt-4o-mini"
    )

    tts = OpenAITTSService(
        api_key=os.getenv("OPENAI_API_KEY"),
        voice="alloy"
    )

    # 3. Configure conversation context
    messages = [
        {
            "role": "system",
            "content": "You are a friendly virtual assistant. Keep your answers concise and natural in 1-2 sentences.",
        },
    ]

    tcontext = OpenAILLMService.create_context(messages)
    tcontext_aggregator = llm.create_context_aggregator(tcontext)

    # 4. Assemble the Pipeline
    pipeline = Pipeline([
        transport.input(),                  # Receive audio stream from WebRTC
        stt,                                # Audio -> Text (Streaming)
        tcontext_aggregator.user(),          # Add user text to context
        llm,                                # LLM generates response (Tokens)
        tts,                                # Text -> Audio (Chunks)
        transport.output(),                 # Play audio over WebRTC
        tcontext_aggregator.assistant(),     # Store bot response in context
    ])

    task = PipelineTask(pipeline, PipelineParams(allow_interruptions=True))

    @transport.event_handler("on_first_participant_joined")
    async def on_first_participant_joined(transport, participant):
        transport.capture_participant_transcription(participant["id"])
        # Bot proactively greets the user
        await task.queue_frames([OpenAILLMService.create_context_frame(messages)])

    runner = PipelineRunner()
    logger.info("Voice Bot is running and ready to connect...")
    await runner.run(task)

if __name__ == "__main__":
    asyncio.run(main())
Step 3: Running and Testing
Start the application from your terminal:
python bot.py
Open the Daily room URL in your browser, unmute your microphone, and start talking. The bot will respond within 500–700ms after you finish speaking. Try interrupting while the bot is talking; you’ll notice it cuts off instantly to listen to your new query.
Production Latency Optimization Tips
To take your Voice Agent from prototype to production-grade deployment, optimize these key parameters:
- Server Region: If your users are located in Southeast Asia, deploy your Pipecat server in Singapore (
ap-southeast-1) to keep WebRTC ping under 35ms. Deploying in the US introduces an unnecessary 200ms round-trip penalty. - Use Conversational-Optimized TTS: Instead of OpenAI TTS (~350ms TTFB), consider Cartesia Sonic (~100–140ms) or ElevenLabs Flash v2.5 (~150ms) for a substantially smoother experience.
- Select LLMs with Ultra-Fast TTFT: Models like
gpt-4o-miniorclaude-3-5-haikuoffer Time to First Token (TTFT) under 250ms, significantly outperforming self-hosted 70B models running on constrained GPU infrastructure. - Fine-Tune VAD Silence Thresholds: In Silero VAD, configure
stop_secsbetween0.25 - 0.35s. This range is responsive enough to detect sentence completion without prematurely cutting off users taking a breath.