Background & Why Your System Needs OLAP
The revenue dashboard spins endlessly for 30 seconds every time your manager switches quarterly filters—sometimes even throwing a 504 Gateway Timeout. This is an all-too-familiar scenario for engineering teams as their data begins to swell.
The initial knee-jerk reaction is often adding more indexes to MySQL or upgrading the PostgreSQL server’s RAM from 16GB to 64GB. However, this quick fix only buys you a few weeks. Once your data exceeds 20 to 50 million rows, the bottlenecks inevitably return.
The root of the problem lies in the underlying storage architecture:
- Transactional Databases (OLTP – MySQL, PostgreSQL): Use row-oriented storage. This design is highly optimized for inserting a new order or fetching a specific user’s details (often under 2ms). However, when computing aggregations (SUM, COUNT, AVG) across tens of millions of records, the engine must scan entire data pages from disk. Disk I/O pegs at 100%, and CPUs instantly spike to capacity.
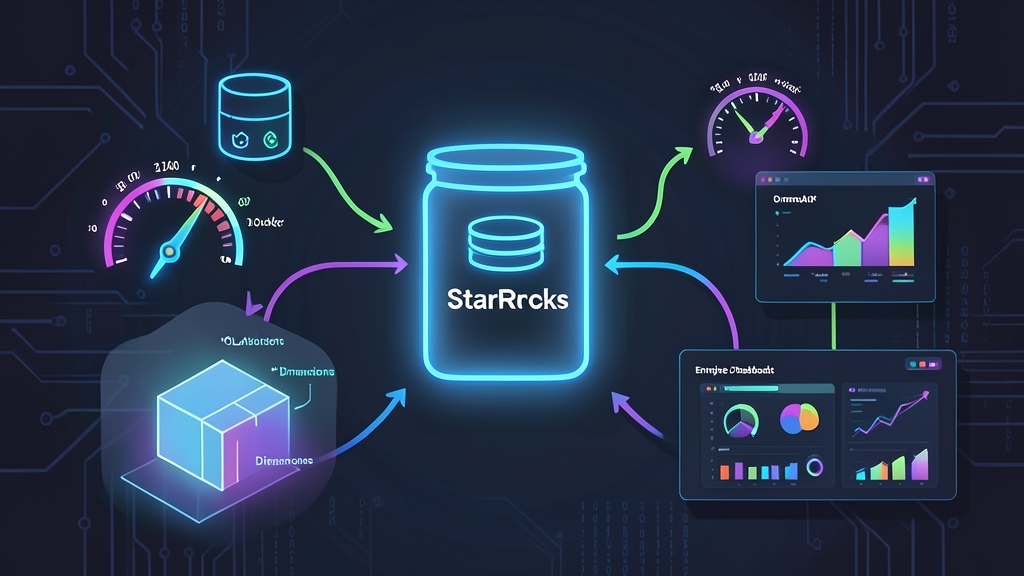
- Analytical Databases (OLAP – StarRocks): Use columnar storage. All values for columns like
priceororder_dateare tightly compressed and stored in contiguous blocks. Need to calculate total revenue? StarRocks scans only the price column and ignores the rest, slashing the volume of data read by 80% to 95%.
StarRocks handles these workloads blazingly fast thanks to its fully vectorized execution engine leveraging CPU SIMD instructions. Complex analytical queries that would take 20 seconds in MySQL often finish in under 150ms. Best of all, StarRocks is fully wire-compatible with the MySQL protocol. You can connect Metabase, Apache Superset, or Tableau directly to port 9030 without rewriting queries or swapping client drivers.
Setting Up a StarRocks Cluster with Docker
StarRocks cleanly decouples into two core components:
- Frontend (FE): Accepts client connections, parses SQL statements, generates optimized execution plans, and manages cluster metadata.
- Backend (BE): Stores columnar data blocks and handles parallel distributed query execution.
For spinning up a local sandbox quickly, Docker Compose is the most convenient tool. Initialize your working directory:
mkdir starrocks-lab && cd starrocks-lab
touch docker-compose.yml
Define the following configuration in docker-compose.yml:
version: '3.8'

services:
  starrocks-fe:
    image: starrocks/fe-ubuntu:3.2-latest
    container_name: starrocks-fe
    hostname: starrocks-fe
    environment:
      - HOST_TYPE=IP
    ports:
      - "8030:8030"  # Web UI
      - "9020:9020"  # FE edit log
      - "9030:9030"  # MySQL Client query port
      - "9242:9242"  # Internal RPC
    networks:
      starrocks-net:
        ipv4_address: 172.20.0.2

  starrocks-be:
    image: starrocks/be-ubuntu:3.2-latest
    container_name: starrocks-be
    hostname: starrocks-be
    environment:
      - HOST_TYPE=IP
    ports:
      - "8040:8040"  # BE Web Server
      - "9050:9050"  # Heartbeat Service Port
      - "9060:9060"  # BE Service Port
    networks:
      starrocks-net:
        ipv4_address: 172.20.0.3
    depends_on:
      - starrocks-fe

networks:
  starrocks-net:
    driver: bridge
    ipam:
      config:
        - subnet: 172.20.0.0/16
Run the following command to start the cluster:
docker compose up -dWait about 30 to 45 seconds for both containers to complete initialization. At this stage, FE and BE run independently and are not yet aware of each other. Connect to the FE via port 9030 using a MySQL client:
# Default user is root with an empty password
mysql -h 127.0.0.1 -P 9030 -u root
If you don’t have a local MySQL client installed, you can invoke the client directly inside the container:
docker exec -it starrocks-fe mysql -P 9030 -u rootRegister the BE node with the cluster using its internal IP address and heartbeat port (9050):
-- Register the BE node under FE management
ALTER SYSTEM ADD BACKEND "172.20.0.3:9050";
Table Design and Loading Sample Data
StarRocks supports four primary table models: Duplicate Key, Aggregate Key, Unique Key, and Primary Key. For append-only transactional records (such as orders or access logs), Duplicate Key offers optimal write throughput and scan performance.
Create a database and an e-commerce orders table:
CREATE DATABASE IF NOT EXISTS retail_analytics;
USE retail_analytics;

CREATE TABLE IF NOT EXISTS orders (
    order_id BIGINT NOT NULL,
    order_date DATE NOT NULL,
    customer_id INT NOT NULL,
    category VARCHAR(50) NOT NULL,
    price DECIMAL(10, 2) NOT NULL,
    quantity INT NOT NULL,
    region VARCHAR(30) NOT NULL
)
ENGINE=OLAP
DUPLICATE KEY(order_id, order_date)
PARTITION BY RANGE(order_date) (
    START ("2024-01-01") END ("2024-12-31") EVERY (INTERVAL 1 MONTH)
)
DISTRIBUTED BY HASH(order_id) BUCKETS 4
PROPERTIES (
    "replication_num" = "1"
);
Key technical details of these settings:
ENGINE=OLAP: Activates the dedicated columnar storage engine.PARTITION BY RANGE: Partitions the table by month to enable data pruning. When querying March data, the engine automatically skips the other 11 months, significantly reducing scanned data volume.DISTRIBUTED BY HASH ... BUCKETS 4: Splits each partition into 4 distributed tablets. An appropriate bucket count allows the engine to fully leverage multi-core CPU parallelism.replication_num = 1: Configured for a single replica since this lab environment only runs one BE node. In a production cluster with at least 3 nodes, set this to 3 for high availability (HA) and fault tolerance.
Insert sample records:
INSERT INTO orders VALUES
(1001, '2024-03-01', 501, 'Electronics', 1200.00, 1, 'Hanoi'),
(1002, '2024-03-02', 502, 'Home & Kitchen', 45.50, 3, 'HCM'),
(1003, '2024-03-02', 503, 'Electronics', 350.00, 2, 'Danang'),
(1004, '2024-03-05', 504, 'Fashion', 85.00, 4, 'Hanoi'),
(1005, '2024-03-10', 505, 'Electronics', 2100.00, 1, 'HCM');
Run a typical dashboard aggregation query to analyze revenue:
SELECT
    category,
    region,
    COUNT(order_id) AS total_orders,
    SUM(price * quantity) AS total_revenue,
    ROUND(AVG(price), 2) AS average_item_price
FROM orders
WHERE order_date >= '2024-03-01'
GROUP BY category, region
ORDER BY total_revenue DESC;
Operations & Monitoring
Distributed systems must be properly verified for node health before handling high production workloads.
1. Checking Cluster Health via MySQL CLI
Verify the status of FE and BE nodes:
-- Check the Frontend node list
SHOW PROC '/frontends';

-- Check the Backend node list
SHOW PROC '/backends'\G;
Pay close attention to two fields in the BE output: Alive should be true and ErrCode must be 0. If Alive: false, verify Docker subnet networking or check the port 9050 logs.
2. Monitoring Metrics via the Web UI
The built-in Web UI provides intuitive resource monitoring. Open your browser and navigate to:
http://localhost:8030Log in as user root (leave the password blank). From here, you can monitor disk usage, per-node RAM consumption, and inspect running queries in real time.
3. Analyzing Execution Performance with Query Profiles
When troubleshooting slow queries over tens of gigabytes, enable profiling to break down execution times stage by stage:
-- Enable profiling for the current session
SET enable_profile = true;

-- Execute the query to diagnose
SELECT category, SUM(price * quantity) FROM orders GROUP BY category;
In the Web UI, open the Queries tab and click on the recent Query ID. You will see a detailed execution graph showing disk scan duration (OLAP_SCAN_NODE), aggregation time (AGGREGATION_NODE), and inter-node network exchange volumes.
Decoupling analytical workloads (OLAP) from operational databases (OLTP) is a crucial step as your system scales. With this lightweight Docker cluster using under 2GB of RAM, you have a solid local sandbox to benchmark query performance before rolling StarRocks out to production.