Quick Start: Set Up a Load Balancer in 5 Minutes
If you already have 3 Ubuntu servers (1 LB + 2 backends), here’s the fastest way to get started:
# Install Nginx on the Load Balancer server
sudo apt update && sudo apt install -y nginx

# Create the config file for the LB
sudo nano /etc/nginx/sites-available/loadbalancer
Paste the following content into the file:
upstream webapp_cluster {
    least_conn;
    server 192.168.1.101:8080;
    server 192.168.1.102:8080;
    server 192.168.1.103:8080;
}

server {
    listen 80;
    server_name yourdomain.com;

    location / {
        proxy_pass http://webapp_cluster;
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    }
}
# Enable and test
sudo ln -s /etc/nginx/sites-available/loadbalancer /etc/nginx/sites-enabled/
sudo nginx -t
sudo systemctl reload nginxThat’s the basics done in 5 minutes. Below, I’ll walk through the details and add SSL.
Understanding the Concepts Before Configuring
What Is SSL Offloading and Why Use It?
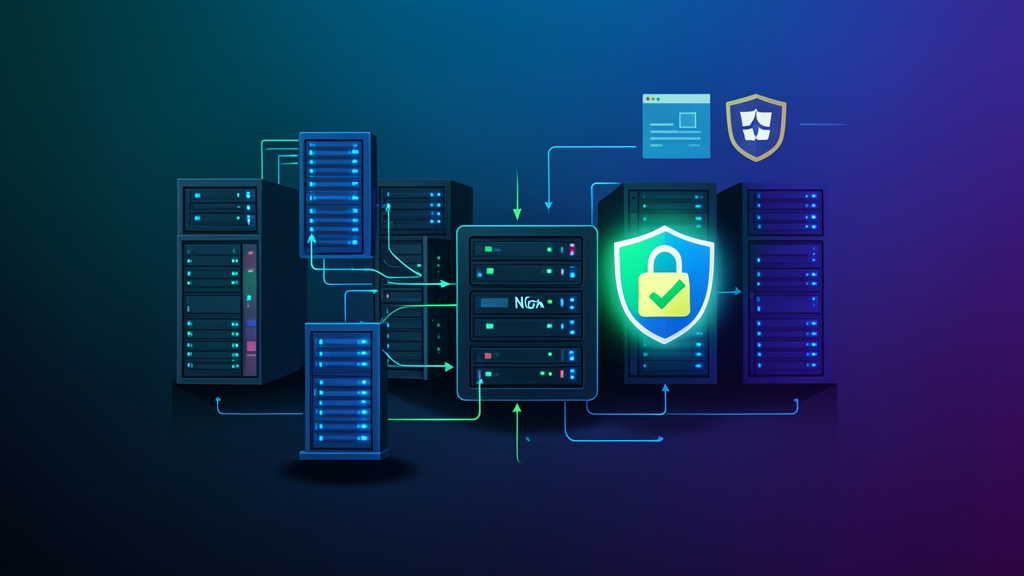
SSL Offloading (also called SSL Termination) means Nginx handles all TLS encryption and decryption instead of your backend servers. The practical benefits:
- Lighter backend servers: no crypto overhead to process
- Centralized certificate management: one cert instead of N certs across N servers
- Plain HTTP for internal traffic: reduced overhead on the LAN
I use this architecture for projects with 2–3 app servers or more. For a single server, a regular reverse proxy is enough — no need to over-engineer it.
Load Balancing Algorithms in Nginx
- Round Robin (default): distributes requests sequentially, ideal when requests have similar processing times
- least_conn: sends requests to the server with the fewest active connections — use this for long-running requests like WebSockets or file uploads
- ip_hash: the same IP always goes to the same server — needed when your app uses server-side sessions, but not recommended for new apps
- weight: distributes traffic by weight — use when servers have different hardware specs
Full Configuration with SSL Offloading
Preparing the SSL Certificate
This blog already has a dedicated post on Let’s Encrypt, so I won’t repeat those steps here. Assuming your certificates are at:
- Certificate:
/etc/letsencrypt/live/yourdomain.com/fullchain.pem - Private key:
/etc/letsencrypt/live/yourdomain.com/privkey.pem
Complete Configuration File
upstream webapp_cluster {
    least_conn;

    server 192.168.1.101:8080 weight=3 max_fails=2 fail_timeout=15s;
    server 192.168.1.102:8080 weight=3 max_fails=2 fail_timeout=15s;
    server 192.168.1.103:8080 weight=1 backup;  # standby server

    keepalive 32;  # maintain connection pool to backend
}

# Redirect HTTP → HTTPS
server {
    listen 80;
    server_name yourdomain.com www.yourdomain.com;
    return 301 https://$host$request_uri;
}

# Main HTTPS server with SSL Offloading
server {
    listen 443 ssl;
    http2 on;
    server_name yourdomain.com www.yourdomain.com;

    # SSL Certificate
    ssl_certificate /etc/letsencrypt/live/yourdomain.com/fullchain.pem;
    ssl_certificate_key /etc/letsencrypt/live/yourdomain.com/privkey.pem;

    # SSL hardening
    ssl_protocols TLSv1.2 TLSv1.3;
    ssl_ciphers ECDHE-ECDSA-AES128-GCM-SHA256:ECDHE-RSA-AES128-GCM-SHA256:ECDHE-ECDSA-AES256-GCM-SHA384:ECDHE-RSA-AES256-GCM-SHA384;
    ssl_prefer_server_ciphers off;
    ssl_session_cache shared:SSL:10m;
    ssl_session_timeout 1d;

    # Security headers
    add_header Strict-Transport-Security "max-age=31536000; includeSubDomains" always;
    add_header X-Frame-Options "SAMEORIGIN" always;
    add_header X-Content-Type-Options "nosniff" always;

    location / {
        proxy_pass http://webapp_cluster;
        proxy_http_version 1.1;
        proxy_set_header Connection "";       # required for upstream keepalive

        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;  # inform the app it's using HTTPS

        # Timeout settings
        proxy_connect_timeout 5s;
        proxy_read_timeout 60s;
        proxy_send_timeout 60s;

        # Buffer settings
        proxy_buffering on;
        proxy_buffer_size 8k;
        proxy_buffers 8 8k;
    }

    # Internal health check endpoint
    location /nginx-health {
        access_log off;
        return 200 "healthy\n";
        add_header Content-Type text/plain;
    }
}
Passive Health Checks and Handling Backend Failures
Nginx Open Source (not Plus) only supports passive health checks — it detects failed servers based on actual failed requests rather than actively probing them. The max_fails and fail_timeout parameters in the upstream block above handle this: if a server fails twice within 15 seconds, Nginx removes it from the pool and retries after 15 seconds.
To view real-time status, add this endpoint:
location /nginx-status {
    stub_status;
    allow 127.0.0.1;
    allow 192.168.1.0/24;  # allow internal network only
    deny all;
}
curl http://localhost/nginx-status
# Active connections: 15
# server accepts handled requests
# 1234 1234 5678
# Reading: 0 Writing: 1 Waiting: 14Advanced: Rate Limiting and Sticky Sessions
IP-based Rate Limiting to Prevent Abuse
http {
    limit_req_zone $binary_remote_addr zone=api_limit:10m rate=100r/m;

    server {
        location /api/ {
            limit_req zone=api_limit burst=20 nodelay;
            proxy_pass http://webapp_cluster;
        }
    }
}
Sticky Sessions Without ip_hash
If your app needs sticky sessions but you want to avoid ip_hash (since users behind NAT would funnel all traffic to a single server), use cookie-based hashing instead:
upstream webapp_cluster {
    hash $cookie_SESSIONID consistent;
    server 192.168.1.101:8080;
    server 192.168.1.102:8080;
}
When the Backend Uses a Self-Signed Certificate
location / {
    proxy_pass https://webapp_cluster;  # backend uses HTTPS
    proxy_ssl_verify off;               # skip cert verification (LAN use only)
    proxy_ssl_session_reuse on;
}
proxy_ssl_verify off should only be used on an internal network. Since traffic between the LB and backends is already within the LAN, self-signed certs are acceptable — there’s no need to purchase certs for internal communication.
Real-World Tips
Log Upstream Info to Trace Which Backend Handled the Request
This is the thing I regret not setting up from the start. I once spent half a day debugging an intermittent issue because I had no idea which backend was handling each request:
log_format upstream_log '$remote_addr - $upstream_addr [$time_local] '
                         '"$request" $status $body_bytes_sent '
                         'upstream_time=$upstream_response_time';

access_log /var/log/nginx/lb_access.log upstream_log;
With this format, each log line tells you exactly which backend IP processed the request and how many milliseconds it took.
Zero-Downtime Reload When Adding or Removing Backends
# DO NOT use restart (it will drop active connections)
sudo nginx -t && sudo systemctl reload nginx

# Check if old workers have finished draining
ps aux | grep nginx
Checking SSL and Response Headers
# Check SSL handshake
openssl s_client -connect yourdomain.com:443 -servername yourdomain.com

# Verify X-Forwarded-Proto header is correct
curl -I https://yourdomain.com | grep -i forwarded

# Monitor logs in real time
sudo tail -f /var/log/nginx/lb_access.log
When I first switched from CentOS to Ubuntu, it took me about a week to get comfortable with the package management system. But the Nginx config itself is identical — what changes is just the file paths and how you manage the service. On Ubuntu you use sites-available/sites-enabled instead of conf.d, and systemctl reload nginx instead of service nginx reload. Once you get used to it, Ubuntu’s organization actually feels cleaner.
One thing that often gets overlooked: don’t forget to tune worker_processes and worker_connections in /etc/nginx/nginx.conf to match your LB server’s CPU count. Ubuntu’s defaults are quite conservative — worker_processes auto and worker_connections 768. For high-traffic load balancers, bump worker_connections to 4096 or higher depending on available RAM.