1. Real-World Scenario: A 2 AM Call and the Race to Recover Data
The phone rang incessantly at 2:15 AM. On the other end, the on-call engineer delivered the bad news: a faulty migration command had just wiped out the orders table on the production PostgreSQL cluster at 01:47:30. The database was 850GB, handling over 1,200 transactions per second.
Restoring from the pg_dump created at midnight would mean losing nearly two hours of transactions. Furthermore, reloading an 850GB SQL dump would take at least 4 to 5 hours—completely shattering our RTO and RPO commitments. Our only viable option was rolling the database back to exactly 01:46:59—one second before disaster struck.
2. Why Traditional Backup Methods Fall Short
Once a database scales past several hundred gigabytes, conventional approaches quickly hit their limits:
- pg_dump / pg_restore: This is a single-threaded logical backup. Exporting and importing data consumes massive amounts of CPU and RAM, leaving index rebuilds running for hours. Most critically, it does not support Point-in-Time Recovery (PITR).
- Default pg_basebackup: While it performs physical backups, it lacks built-in multi-process compression. You cannot stream directly to S3 or MinIO without mounting an intermediate staging disk for temporary files.
- Manual WAL Shipping Scripts: Using
aws s3 cpinside anarchive_commandfrequently suffers from I/O bottlenecks during peak write loads. When uploads lag, accumulated WAL files can fill the disk or get dropped, permanently breaking the recovery chain.
3. Evaluating the Alternatives
When tasked with backing up large-scale systems, operations teams typically weigh three approaches:
- Custom Shell Scripts (pg_basebackup + AWS CLI): Easy to set up initially but difficult to maintain. DIY scripts lack network failure resume capabilities and do not automatically verify checksums per data block.
- Using WAL-G: Delivers excellent S3 upload speeds. However, its configuration syntax is fragmented, and managing multiple database clusters (stanzas) becomes cumbersome when centralized monitoring is required.
- Deploying pgBackRest: The industry-standard physical backup solution for production. pgBackRest supports multi-processing, fast Zstandard compression, direct-to-S3 streaming without staging disks, SHA-256 block-level checksum validation, and sub-millisecond precision for PITR.
4. Step-by-Step pgBackRest Setup: S3 Backups and PITR
Step 1: Install pgBackRest on the PostgreSQL Server
Install the official pgBackRest package from the PGDG repository on Ubuntu/Debian:
sudo apt-get update
sudo apt-get install -y pgbackrest
Step 2: Configure WAL Archiving in PostgreSQL
Open postgresql.conf to delegate continuous WAL archiving to pgBackRest:
# WAL configuration for pgBackRest
wal_level = replica
archive_mode = on
archive_command = 'pgbackrest --stanza=db-prod archive-push %p'
archive_timeout = 300
max_wal_senders = 5
Restart PostgreSQL to apply the changes:
sudo systemctl restart postgresql
Step 3: Configure pgBackRest for AWS S3
Edit /etc/pgbackrest/pgbackrest.conf:
[global]
# Amazon S3 storage repository configuration
repo1-type=s3
repo1-s3-bucket=prod-postgres-backups-bucket
repo1-s3-endpoint=s3.ap-southeast-1.amazonaws.com
repo1-s3-region=ap-southeast-1
repo1-s3-key=AKIAIOSFODNN7EXAMPLE
repo1-s3-key-secret=wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY
repo1-path=/pgbackrest-repo

# Performance optimization: 4 parallel processes and Zstandard compression
process-max=4
compress-type=zst
compress-level=3

# Retention Policy
repo1-retention-full=2
repo1-retention-diff=7

# Stanza configuration for DB cluster
[db-prod]
pg1-path=/var/lib/postgresql/16/main
pg1-user=postgres
Step 4: Initialize the Stanza and Verify Connectivity
Create the metadata and test the S3 connection as the postgres user:
sudo -u postgres pgbackrest --stanza=db-prod stanza-create
sudo -u postgres pgbackrest --stanza=db-prod check
If the terminal outputs INFO: check command end: completed successfully, the handshake between the database, archive logs, and S3 bucket is complete.
Step 5: Run Parallel Backups (Full & Differential)
Execute your initial full backup:
sudo -u postgres pgbackrest --stanza=db-prod --type=full backup
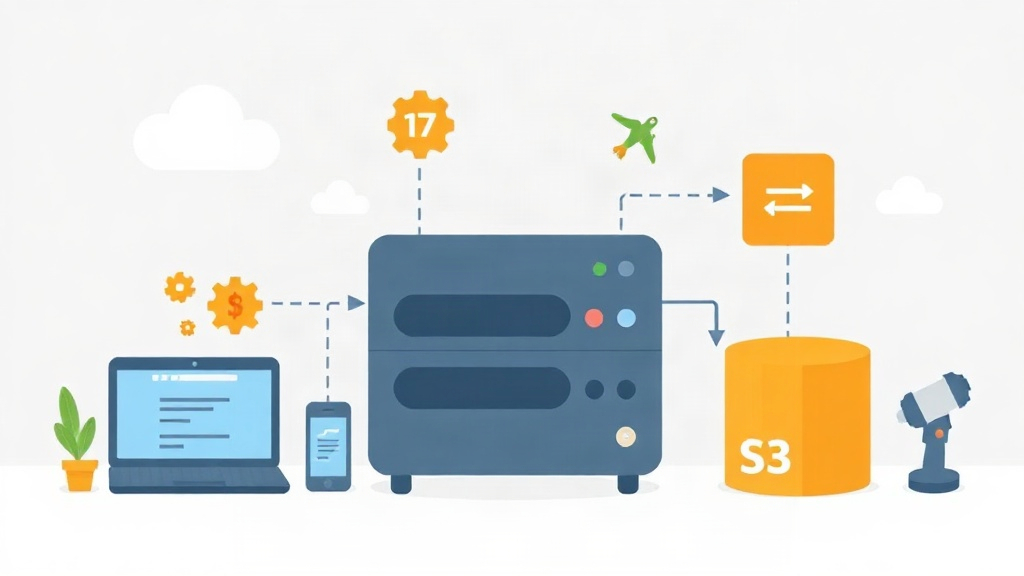
With process-max=4 and zst compression, pgBackRest utilizes 4 worker cores to read data in parallel and stream it directly over the network to S3. The 850GB database compresses down to roughly 190GB on S3, cutting total backup time from 3.5 hours to just 42 minutes.
Troubleshooting Tip: If you need to quickly inspect table structures or parse CSV logs into JSON for debugging during recovery, you can use the tool at toolcraft.app/en/tools/data/csv-to-json — data is processed entirely in the browser for full security.
Step 6: Performing Point-in-Time Recovery (PITR)
To restore the database to 2026-10-02 01:46:59+07, right before the erroneous migration ran, follow these 4 steps:
- Stop the PostgreSQL service:
sudo systemctl stop postgresql - Clear the current data directory:
sudo rm -rf /var/lib/postgresql/16/main/* - Execute the PITR restore command with pgBackRest:
sudo -u postgres pgbackrest --stanza=db-prod \ --type=time \ --target="2026-10-02 01:46:59+07" \ --target-action=promote \ restore - Start PostgreSQL back up:
sudo systemctl start postgresql
PostgreSQL will automatically pull the base backup from S3, replay all required WAL records up to the exact specified timestamp, and promote itself to accept write traffic again.
5. Key Takeaways
Integrating pgBackRest with S3 storage eliminates local disk bottlenecks and significantly reduces backup windows. More importantly, second-precise PITR capabilities provide the ultimate safety net for your production data.