Up and Running in 5 Minutes — See Results First, Understand Later
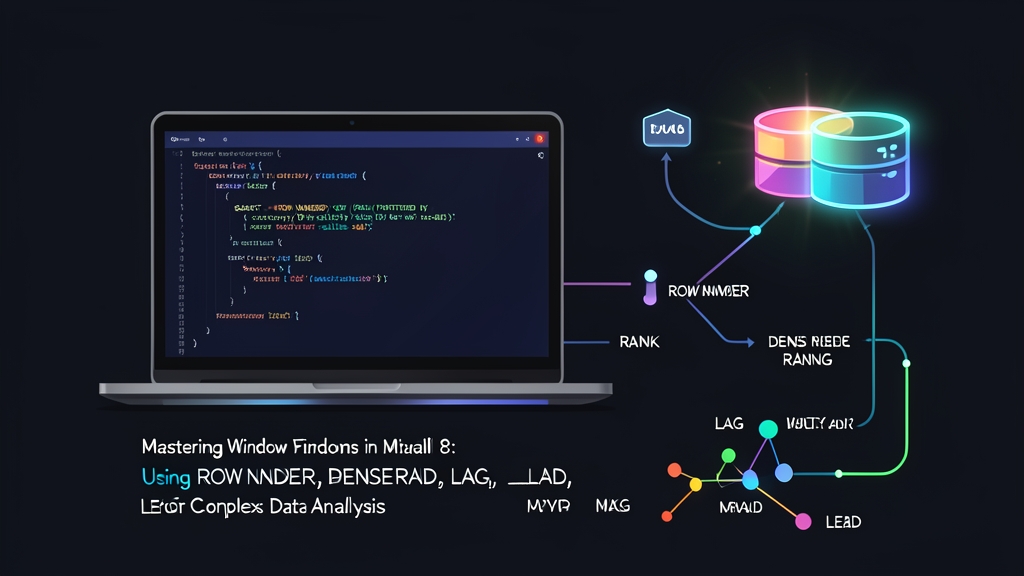
Still writing 3–4 levels of nested subqueries just to rank employees? Or using a self-join to compare this month’s sales against last month? MySQL 8 Window Functions solve both in a single query — no extra subqueries, no extra joins. Ranking, comparing adjacent rows, running totals: all written directly in SELECT.
Create a test table and try it right away:
CREATE TABLE sales (
  id INT AUTO_INCREMENT PRIMARY KEY,
  employee_name VARCHAR(50),
  department VARCHAR(50),
  sale_amount DECIMAL(10,2),
  sale_date DATE
);

INSERT INTO sales (employee_name, department, sale_amount, sale_date) VALUES
('Minh', 'Tech', 15000000, '2024-01-15'),
('Lan',  'Tech', 22000000, '2024-01-16'),
('Hùng', 'Sales', 18000000, '2024-01-15'),
('Thảo', 'Sales', 18000000, '2024-01-17'),
('Nam',  'Tech', 22000000, '2024-01-18'),
('Hoa',  'Sales', 25000000, '2024-01-19'),
('Khoa', 'Tech', 12000000, '2024-01-20');
-- Rank employees within each department — 3 functions side by side for comparison
SELECT
employee_name,
department,
sale_amount,
ROW_NUMBER() OVER (PARTITION BY department ORDER BY sale_amount DESC) AS row_num,
RANK() OVER (PARTITION BY department ORDER BY sale_amount DESC) AS rnk,
DENSE_RANK() OVER (PARTITION BY department ORDER BY sale_amount DESC) AS dense_rnk
FROM sales;Once you run it, notice that Lan and Nam both have 22 million but the three functions give completely different results. The section below explains each case.
Detailed Explanation: What Each Function Does
ROW_NUMBER() — Absolute Row Number, Never Duplicated
Even when two rows have the same value, ROW_NUMBER still assigns different numbers. The ordering of tied rows is non-deterministic — the engine decides, and you can’t predict it. Add a tie-breaker column to ORDER BY (e.g., id after sale_amount DESC) to get consistent results across runs.
-- Get exactly 1 top-selling employee per department (never returns 2 rows)
SELECT * FROM (
  SELECT
    employee_name, department, sale_amount,
    ROW_NUMBER() OVER (PARTITION BY department ORDER BY sale_amount DESC) AS rn
  FROM sales
) t
WHERE rn = 1;
RANK() — Ties Allowed, Next Number Skipped
Lan and Nam both have 22 million → both get rank 1. The next rank jumps to 3, skipping 2. This makes sense for real-world leaderboards: when two people perform equally well, neither deserves to be called second place.
-- Top 2 per department — may return 3 rows if there's a tie at rank 1
SELECT * FROM (
  SELECT
    employee_name, department, sale_amount,
    RANK() OVER (PARTITION BY department ORDER BY sale_amount DESC) AS rnk
  FROM sales
) t
WHERE rnk <= 2;
DENSE_RANK() — Ties Allowed, Consecutive Numbers Without Gaps
Essentially the same as RANK but without the number gaps. Tied at rank 1 → next is 2, not 3. Great for group reports: group top-1, group top-2, group top-3 — the rank numbers carry clearer meaning.
-- Clear comparison showing the difference
SELECT
  employee_name,
  sale_amount,
  RANK()       OVER (ORDER BY sale_amount DESC) AS rank_val,
  DENSE_RANK() OVER (ORDER BY sale_amount DESC) AS dense_val
FROM sales;
-- Hoa: 25M → rank 1 / dense 1
-- Lan, Nam: 22M → rank 2 / dense 2
-- Hùng, Thảo: 18M → rank 4 / dense 3  ← this is the key difference
LAG() and LEAD() — Comparing with Adjacent Rows
Personally, these are the functions I use most when building monthly reports. LAG() pulls the value from the previous row, LEAD() looks at the next row — both within the same partition and sort order.
-- Calculate % change in sales compared to each employee's previous transaction
SELECT
  employee_name,
  sale_date,
  sale_amount,
  LAG(sale_amount)  OVER (PARTITION BY employee_name ORDER BY sale_date) AS prev_sale,
  LEAD(sale_amount) OVER (PARTITION BY employee_name ORDER BY sale_date) AS next_sale,
  ROUND(
    (sale_amount - LAG(sale_amount) OVER (PARTITION BY employee_name ORDER BY sale_date))
    / LAG(sale_amount) OVER (PARTITION BY employee_name ORDER BY sale_date) * 100, 2
  ) AS pct_change
FROM sales;
LAG/LEAD accepts up to 3 parameters: LAG(column, offset, default). Offset defaults to 1, and default is NULL when there’s no previous/next row:
-- Get value 2 rows back, return 0 if it doesn't exist
LAG(sale_amount, 2, 0) OVER (PARTITION BY department ORDER BY sale_date)
Advanced — Real-World Combination Techniques
Running Total with SUM() OVER and Frame Clause
Ranking functions are just the tip of the iceberg. SUM, AVG, MAX, and MIN all work with OVER — and frame clause is where this feature becomes truly powerful:
SELECT
  employee_name,
  department,
  sale_date,
  sale_amount,
  -- Running total within department by date
  SUM(sale_amount) OVER (
    PARTITION BY department
    ORDER BY sale_date
    ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
  ) AS running_total,
  -- Department average (independent of ORDER BY)
  AVG(sale_amount) OVER (PARTITION BY department) AS dept_avg
FROM sales
ORDER BY department, sale_date;
Named Window — Write Once, Reuse Many Times
Multiple functions using the same partition and order? Instead of copy-pasting 4 times, MySQL 8 lets you name a window and reuse it. Changing the partition logic means changing just one place:
SELECT
  employee_name,
  department,
  sale_amount,
  ROW_NUMBER() OVER w AS row_num,
  RANK()       OVER w AS rnk,
  DENSE_RANK() OVER w AS dense_rnk,
  LAG(sale_amount) OVER w AS prev_amount
FROM sales
WINDOW w AS (PARTITION BY department ORDER BY sale_amount DESC);
-- Instead of repeating (PARTITION BY department ORDER BY sale_amount DESC) 4 times
Combining with CTE for Complex Queries
CTEs and Window Functions combine naturally: the CTE computes rank and dept_avg in a single scan, and the outer query just filters on the results — not a single nested subquery in sight:
-- Get employees with above-average department sales, with their rank in the department
WITH dept_ranked AS (
  SELECT
    employee_name,
    department,
    sale_amount,
    AVG(sale_amount) OVER (PARTITION BY department) AS dept_avg,
    DENSE_RANK() OVER (PARTITION BY department ORDER BY sale_amount DESC) AS dept_rank
  FROM sales
)
SELECT
  employee_name,
  department,
  sale_amount,
  ROUND(dept_avg, 0) AS dept_avg,
  dept_rank
FROM dept_ranked
WHERE sale_amount > dept_avg
ORDER BY department, dept_rank;
Detecting Gaps in a Data Sequence
A small but useful trick: LEAD() can also detect missing IDs in a sequence, without needing a self-join:
-- Find missing IDs in a sequence
SELECT
  id,
  LEAD(id) OVER (ORDER BY id) AS next_id,
  LEAD(id) OVER (ORDER BY id) - id - 1 AS gap_size
FROM sales
HAVING gap_size > 0;
Practical Tips from Experience
1. Run EXPLAIN ANALYZE Before Deploying
My production database runs MySQL 8.0 with about 50GB of data. I once had a window function query time out at 15 seconds on a transaction table with 8 million rows — after adding a composite index, it dropped to 0.3 seconds. Why so slow? Window Functions must buffer the entire partition into RAM before computing. Always check before deploying:
EXPLAIN ANALYZE
SELECT
  employee_name,
  RANK() OVER (PARTITION BY department ORDER BY sale_amount DESC) AS rnk
FROM sales;
-- Note: "Using temporary" and "Using filesort" in the output
-- If you see large tmp disk usage → need index or pre-aggregate
2. Index Correctly — Partition Column First, Order Column Second
-- For PARTITION BY department ORDER BY sale_amount
CREATE INDEX idx_dept_sale ON sales (department, sale_amount DESC);

-- Covering index if SELECT only needs a few columns
CREATE INDEX idx_dept_sale_cover ON sales (department, sale_amount DESC, employee_name);
3. Understand ROWS vs RANGE
The most common source of confusion when first using frame clause:
-- ROWS: counts exactly N physical rows
SUM(sale_amount) OVER (
  ORDER BY sale_date
  ROWS BETWEEN 2 PRECEDING AND CURRENT ROW
)
-- → Sums the 3 most recent rows (physical), regardless of value

-- RANGE: counts by value range, ties are grouped together
SUM(sale_amount) OVER (
  ORDER BY sale_date
  RANGE BETWEEN INTERVAL 7 DAY PRECEDING AND CURRENT ROW
)
-- → Sums all rows within the last 7 days
Use RANGE when the logic is “within a value/time range.” Use ROWS when you need exactly N rows.
4. Avoid Using ROW_NUMBER as a LIMIT Replacement on Large Tables
Using ROW_NUMBER for pagination sounds clever, but MySQL scans the entire table and assigns a row number to every row before filtering — the cost is no different from a regular OFFSET. Tables under 100k rows: acceptable. Million-row tables and above: switch to keyset pagination.
If you’re considering upgrading from MySQL 5.7 to 8.x, Window Functions are the most compelling practical reason to do it. Problems that once required 3–4 levels of nested subqueries now fit neatly into a single CTE + window clause. Shorter code, easier to maintain — and the query planner optimizes better without nested subqueries to parse.